Open research · September 20, 2026
CHI / CHIS
A Human-Referenced Framework for Longitudinal Evaluation of Artificial Cognitive Systems
Dmitry Chistyakov · Version 0.1
Start with the article
Beyond Intelligence: Introducing CHI and CHIS for Measuring Human-Like Machine Cognition connects memory architecture to testable questions about retention, change and experience.
What the release contains
- Separate capacity and human-similarity profiles across R, M, C, A and I; optional geometric CHI.
- Effective Indexed Memory Capacity and full memory-quality curves with explicit budgets and censoring.
- CHIS continuity, drift, plasticity, stability, recovery, hysteresis, accumulation and divergence measures.
- Thirty test templates, human-calibration requirements, controlled history experiments and uncertainty rules.
- Standard-library Python utilities, a synthetic demo, JSONL records and verification tests.
Reproduce the scoring demo
python -m unittest -v
python chi_chis.py demo --output demo --seed 42
python chi_chis.py score examples/score.json
python chi_chis.py sweep examples/sweep.json
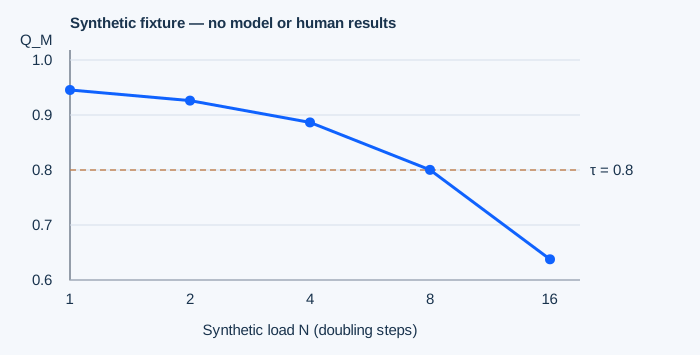
The demo uses eight synthetic clusters, five checkpoints and a tiny load grid. It does not execute the 30-test panel or evaluate a real model. Read the README for formats, assumptions and limits.
Compile the paper
pdflatex -interaction=nonstopmode -halt-on-error main.tex
bibtex main
pdflatex -interaction=nonstopmode -halt-on-error main.tex
pdflatex -interaction=nonstopmode -halt-on-error main.tex
Standard article class, Latin Modern fonts, BibTeX and vector diagrams drawn in LaTeX. The archive contains only six source/bibliography files. Local verification used Tectonic; the source is prepared for standard LaTeX processing.
Separate empirical pilot
View measured model-and-notebook results. This new, limited experiment is separate from the original proposal and does not provide human-calibrated CHI scores.
Research status
The next step is empirical calibration and reliability testing, with independently replicated trajectories and matched baselines. This page makes no claim of arXiv acceptance or peer review.